
- Project
- Our own product
- Our role
- Product · Mobile development · AI pipeline · Backend
- Duration
- 5 months
01 / Behind the product
A real need. A considered solution.
Challenge
Most consumer "face score" apps are a single number from a single model call. The same photo can score 6.8 / 7.4 / 8.1 across calls; lighting, angle and filters decide the result. Try-on tools usually break identity too. And there is cost: every photo and every coach message is real money.
Approach
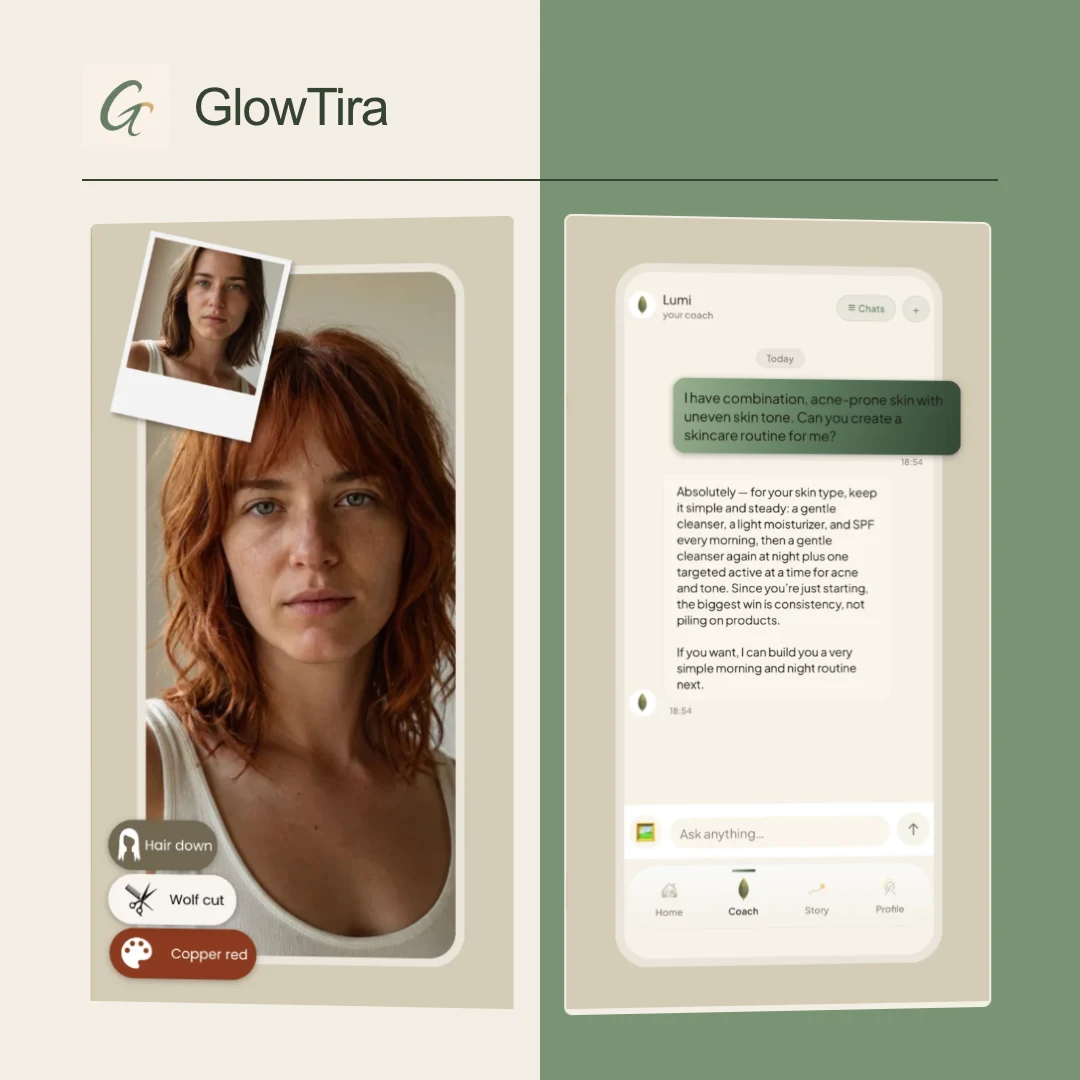
Scoring is a seven-stage pipeline: a photo quality gate from a 64×64 luminance probe before upload (no call is spent on a bad photo), one rubric-grounded vision call with 0.5-wide bands across six dimensions, anti-gaming calibration, temporal smoothing with a seven-day EWMA, weighting by the user’s goals, an uncertainty interval per dimension and three concrete moves with expected lift.
The rubric cut variance from ±1.5 to ±0.3. Hair and beard try-ons use face-aware FLUX Kontext, outfits and accessories use FLUX.2 Edit. The trust boundary is the Edge Function: no provider key ships in the bundle, rate limits are atomic in a Postgres RPC keyed by subscription tier, a double tap collapses into one request, and coach memory is written only on the server.
Result
Live on the App Store in six languages. 29 Edge Functions, nightly trend updates and weekly memory compaction via pg_cron, a RevenueCat webhook. Tests run offline on Node’s own runner; remote tests refuse the known production project.
02 / Inside the product
The experience, on screen.
Open a screen to explore the details.06 images
03 / Scope & details
The details make the experience.
- 01
Seven-stage scoring pipeline: quality gate, rubric, calibration, EWMA, uncertainty interval
- 02
Rubric cuts score variance from ±1.5 to ±0.3
- 03
Face-aware hair and beard try-on (FLUX Kontext)
- 04
Edge Function trust boundary: no provider key in the bundle, rate limits in the database
- 05
Six languages, 29 Edge Functions
Technology
INSIDE THE PRODUCT
The engineering behind the interface.
Systems we built and concrete problems we addressed in this project.
The quality gate runs before any call
A 64×64 luminance probe estimates sharpness (variance), exposure (mean luminance) and centring on device. An unusable photo gets a retake tip and no vision call is spent; a borderline photo’s gate score widens the uncertainty interval on every dimension.
Without a rubric the model drifts
Each of six dimensions has six 0.5-wide bands from 5.0 to 10.0 with observable criteria per band; the model picks the band first and then places the score inside it. Run-to-run swing on the same photo dropped from ±1.5 to ±0.3, and a seven-day EWMA smooths the rest.
Rate limits in the database, single-flight on the client
consume_rate_limit(user_id, bucket) is a SECURITY DEFINER RPC doing an atomic INSERT … ON CONFLICT on rate_limit_quotas keyed by (bucket, tier), with the tier read from users.subscription_status. On the client, singleFlight coalesces concurrent calls for the same (action, userId) into one network request.
Your idea could be next.
What could we build for you?
From a first release to a growing platform. Let’s plan the design, development and launch together.
From Türkiye to the US, UK, Australia and everywhere in between.